
An interactive offline analysis tool for CockroachDB workload-exporter zips. The binary is named workload-analyzer.
Point it at a zip file, and a browser opens with 26 preloaded diagnostic queries and a free SQL editor backed by DuckDB; no database server, no cloud, no data leaves your machine.
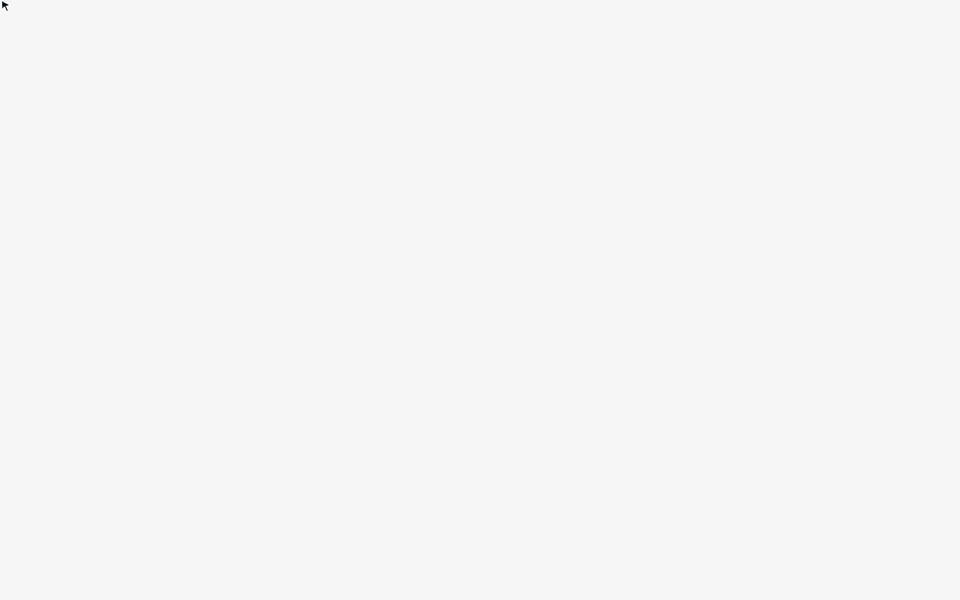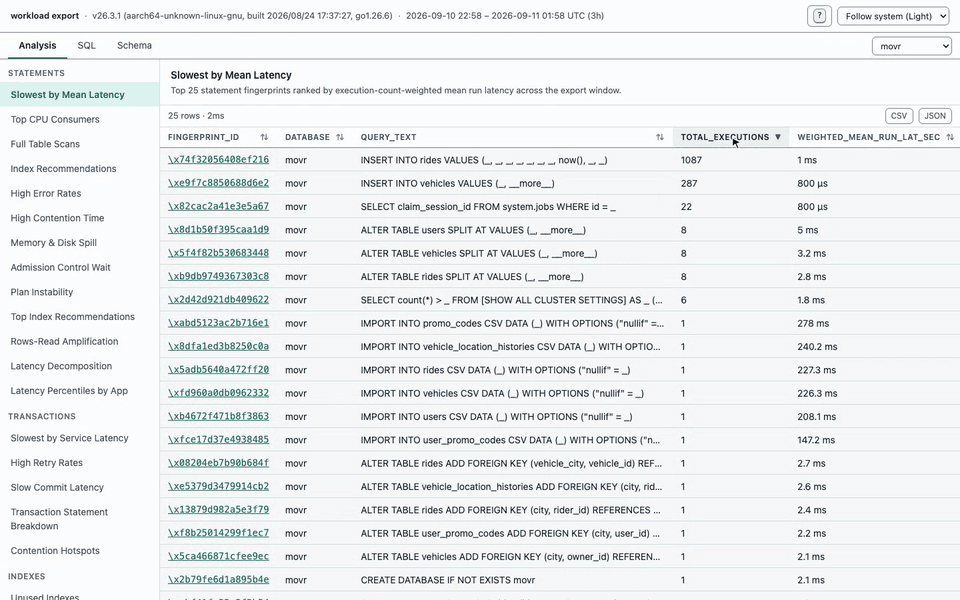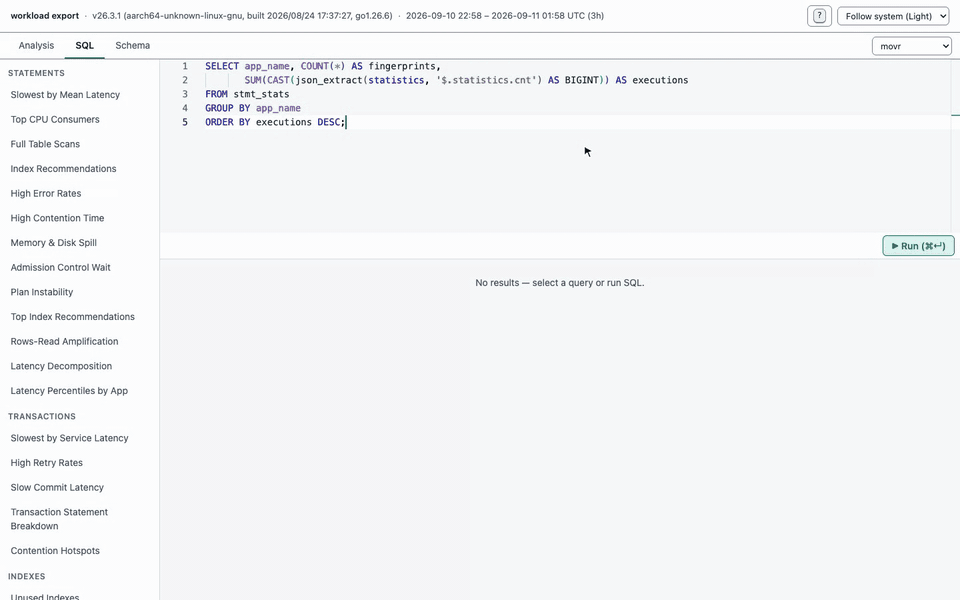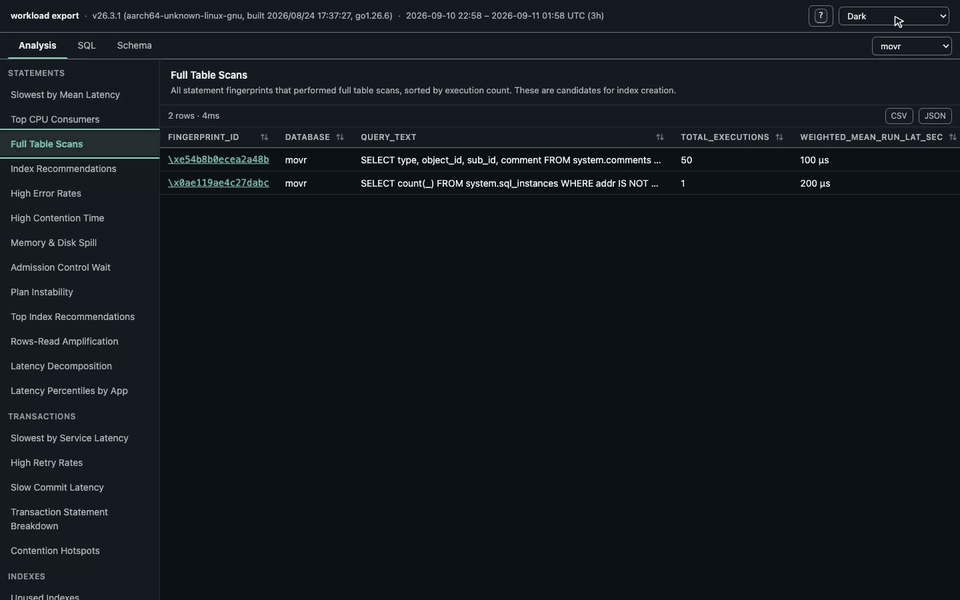
Watch as MP4· recorded from the movr sample export
Grab a prebuilt binary from the latest release (macOS arm64, Linux x86-64), verify the checksum, and run it:
tar -xzf workload-analyzer_*_darwin_arm64.tar.gz
# macOS only, first run: clear the quarantine attribute
xattr -d com.apple.quarantine ./workload-analyzer 2>/dev/null || true
./workload-analyzer path/to/export.zip
No runtime dependencies. The binary is self-contained. Or build from source.
workload-analyzer 2025-05-29-cutover.zip
# → extracts zip to temp dir
# → loads CSVs into in-memory DuckDB (large files load in background)
# → opens http://localhost:8080 in your browser
# → Ctrl-C to stop, temp dir is cleaned up automatically
The tool ships as a single binary. The React frontend is embedded via go:embed, so nothing extra needs to be installed to run it.
Three tabs:
| Tab | What it does |
|---|---|
| Analysis | Click any of the 26 preloaded queries in the sidebar — results appear immediately. Click a fingerprint_id to open a resizable drawer with the query text and per-statement stats (transactions resolve to their constituent statements), with a button to copy the contents. |
| SQL | Free-form DuckDB SQL editor (Monaco). Press Cmd+Enter / Ctrl+Enter to run. |
| Schema | Raw DDL from the export's .schema.txt files, one database per dropdown. |
Any result grid (Analysis or SQL) sorts client-side: click a column header to cycle ascending → descending → original order. Numeric columns (including bigint/decimal values the export ships as strings) sort numerically, other columns lexically, and NULLs always sort last. CSV/JSON export reflects the current sorted order.
The UI is keyboard-navigable: 1/2/3 switch tabs, j/k step through the query list (arrow keys work when the tab bar or list has focus), and ? opens a dialog listing every shortcut.
| Category | Query |
|---|---|
| Statements | Slowest by Mean Latency |
| Statements | Top CPU Consumers |
| Statements | Full Table Scans |
| Statements | Index Recommendations |
| Statements | High Error Rates |
| Statements | High Contention Time |
| Statements | Memory & Disk Spill |
| Statements | Admission Control Wait |
| Statements | Plan Instability |
| Statements | Top Index Recommendations |
| Statements | Rows-Read Amplification |
| Statements | Latency Decomposition |
| Statements | Latency Percentiles by App |
| Transactions | Slowest by Service Latency |
| Transactions | High Retry Rates |
| Transactions | Slow Commit Latency |
| Transactions | Transaction Statement Breakdown |
| Transactions | Contention Hotspots |
| Indexes | Unused Indexes |
| Indexes | Rarely Used Indexes |
| Indexes | Table Statistics Audit |
| Indexes | Stale Table Statistics |
| Cluster | Non-Default Cluster Settings |
| Cluster | Node CPU & Memory |
| Cluster | Non-Default Settings (System VC) |
| Cluster | Persisted System Settings |
All queries use DuckDB JSON path extraction against the CSV files in the export; they run entirely in-process, no network calls.
Use the cockroach workload-exporter tool:
export COCKROACH_URL="postgresql://<user>:<pass>@<host>:<port>/<db>?<ssl_opts>"

workload-exporter export \
  --start "$(date -u -v-8H +%Y-%m-%dT%H:%M:%SZ)" \
  --end   "$(date -u -v-30M +%Y-%m-%dT%H:%M:%SZ)" \
  --output-file "$(date +%Y-%m-%d)-export.zip"
The
--endoffset of 30 minutes accounts forsql.stats.flush.interval(default 10 min) — the most recent window may not have flushed yet.
workload-analyzer <zip>
  ├── Extract zip → OS temp dir (removed on exit)
  ├── Parse metadata.json + *.schema.txt
  ├── Load CSVs into in-memory DuckDB
  │     small tables first → statement_statistics.csv last (~1 GB)
  │     HTTP server starts immediately; UI shows a progress bar while loading
  └── Serve embedded React SPA at http://localhost:<port>

Binary layout:
  main.go          CLI entry point, signal handling, server lifecycle
  static.go        go:embed of web/dist → SPA file server with index.html fallback
  internal/
    loader/        zip extraction, DuckDB open/load, metadata/schema parsing
    catalog/       26 preloaded Query structs with verified DuckDB SQL
    api/           6 read-only HTTP endpoints (status, meta, queries, run, schema, databases)
  web/             React + Vite + TypeScript source
    src/api.ts     typed fetch wrappers
    src/hooks/     useStatus (polling), useRun (SQL execution)
    src/components/ LoadingScreen, ResultsTable, QueryList, tab components
Key design choices:
- Native DuckDB (
github.com/marcboeker/go-duckdbvia CGo) — avoids WASM memory limits, reads CSVs directly withread_csv_auto. - Progressive loading — the server starts as soon as the zip is extracted; the large
statement_statistics.csvloads last in a background goroutine. The UI polls/api/statusand shows progress. - Single binary —
go:embed all:web/distbundles the compiled SPA. One file to distribute, no runtime dependencies. - Read-only — once loaded, the export database is reopened in DuckDB's read-only mode, so the engine itself refuses any statement that would change it. The tool never writes back to any cluster.
The tool runs locally, on your own machine, against your own export. The free-form SQL tab executes arbitrary DuckDB SQL by design, so several guards keep that scoped:
- Loopback only — the HTTP server binds to
127.0.0.1, so/api/runis not reachable from the network. - Cross-site requests refused — loopback binding alone doesn't stop your own browser: any website you visit can fire cross-origin requests at
http://localhost:<port>. The server rejects requests whoseOriginis not a loopback origin (CSRF) and requests whoseHostheader is not a loopback name (DNS rebinding). - Read-only after load — the export is loaded into a DuckDB database file in the same per-run temp directory as the extracted CSVs. Once loading completes, that file is closed and reopened with
access_mode=read_only, so DuckDB itself rejectsDROP,INSERT,UPDATE,ALTER,CREATE,ATTACHand every other statement that would change the export — this is enforced by the engine, not by filtering SQL text. ScratchCREATE TEMP TABLEs are still allowed; they live outside the export and vanish with the session. (DuckDB can't switch a running database to read-only and won't open an in-memory one read-only at all, which is why the export lives in a file rather than in memory.) - No file access after load — at the same time, DuckDB's
enable_external_accessis switched off (a one-way switch DuckDB won't let a query re-enable) and the configuration is locked withlock_configuration, so no setting can be changed from SQL afterwards. The SQL editor can run arbitrary read-only SQL over the loaded tables, but can't read other files on disk viaread_csv/COPY/ATTACH. Free-form SQL is refused until this lockdown is in place — "ready" means loaded, read-only and hardened — so there is no window where user-supplied SQL runs with write or file access. - Local & ephemeral — nothing is written back to any cluster; the extracted CSVs and the DuckDB file live only in a temp directory that is removed on exit.
To run the binary: nothing (the binary is self-contained).
To build from source:
- Go 1.24+ with CGo enabled (requires a C compiler —
gccorclang).go.modpinstoolchain go1.26.6, which the Go toolchain fetches automatically. - Node.js 18+ and npm (to build the React frontend)
On macOS: brew install go gcc node
On Linux (Debian/Ubuntu): apt install golang gcc nodejs npm
git clone <this-repo>
cd workload-analyzer
make build
This runs npm install && npm run build in web/, then CGO_ENABLED=1 go build -o workload-analyzer ..
The resulting workload-analyzer binary is self-contained — copy it anywhere and run it.
./workload-analyzer path/to/export.zip

# Custom port:
./workload-analyzer --port 9090 path/to/export.zip

# Print version:
./workload-analyzer --version
A browser window opens automatically. On Linux servers without a display, open http://localhost:<port> manually.
Queries against a table your export doesn't include (e.g. node_cpu_mem / gossip_nodes are absent from application-virtual-cluster exports) return a plain "not in this export" message instead of a raw error.
# Run all tests
make test

# Backend only
CGO_ENABLED=1 go test ./...

# Frontend only
cd web && npm test -- --run

# Integration test against a real export
CGO_ENABLED=1 go test -tags integration -v -run TestIntegration -timeout 10m

# Hot-reload frontend (proxies /api to a running backend)
./workload-analyzer path/to/export.zip &
cd web && npm run dev # → http://localhost:5173The backend exposes six read-only JSON endpoints:
| Endpoint | Description |
|---|---|
GET /api/status |
Loading state, progress (0–1), per-table status |
GET /api/meta |
Cluster version, org, export time range |
GET /api/queries |
Catalog of 26 query descriptors (add ?full=1 to include SQL) |
POST /api/run |
Execute arbitrary DuckDB SQL ({"sql":"..."}) or a catalog query ({"query_id":"...","db":"..."}) |
GET /api/schema |
Raw DDL text, keyed by database name |
GET /api/databases |
Distinct database names in the statement stats (for the filter picker) |
The following tables are available in the SQL editor:
| Table | Source CSV |
|---|---|
stmt_stats |
crdb_internal.statement_statistics.csv |
txn_stats |
crdb_internal.transaction_statistics.csv |
txn_contention |
crdb_internal.transaction_contention_events.csv |
idx_usage |
crdb_internal.index_usage_statistics.csv |
table_indexes |
crdb_internal.table_indexes.csv |
cluster_settings |
crdb_internal.cluster_settings.csv |
table_stats |
system.table_statistics.csv |
node_cpu_mem |
crdb_internal.node_cpu_mem.csv |
This tool builds on work by Cockroach Labs:
- It reads exports produced by the
workload-exportertool. - It was inspired by
ziplook. - Most of the preloaded diagnostic queries are adapted from
cockroachdb-skills, which is likewise Apache 2.0 licensed.
Licensed under the Apache License, Version 2.0. See NOTICE for attributions.