
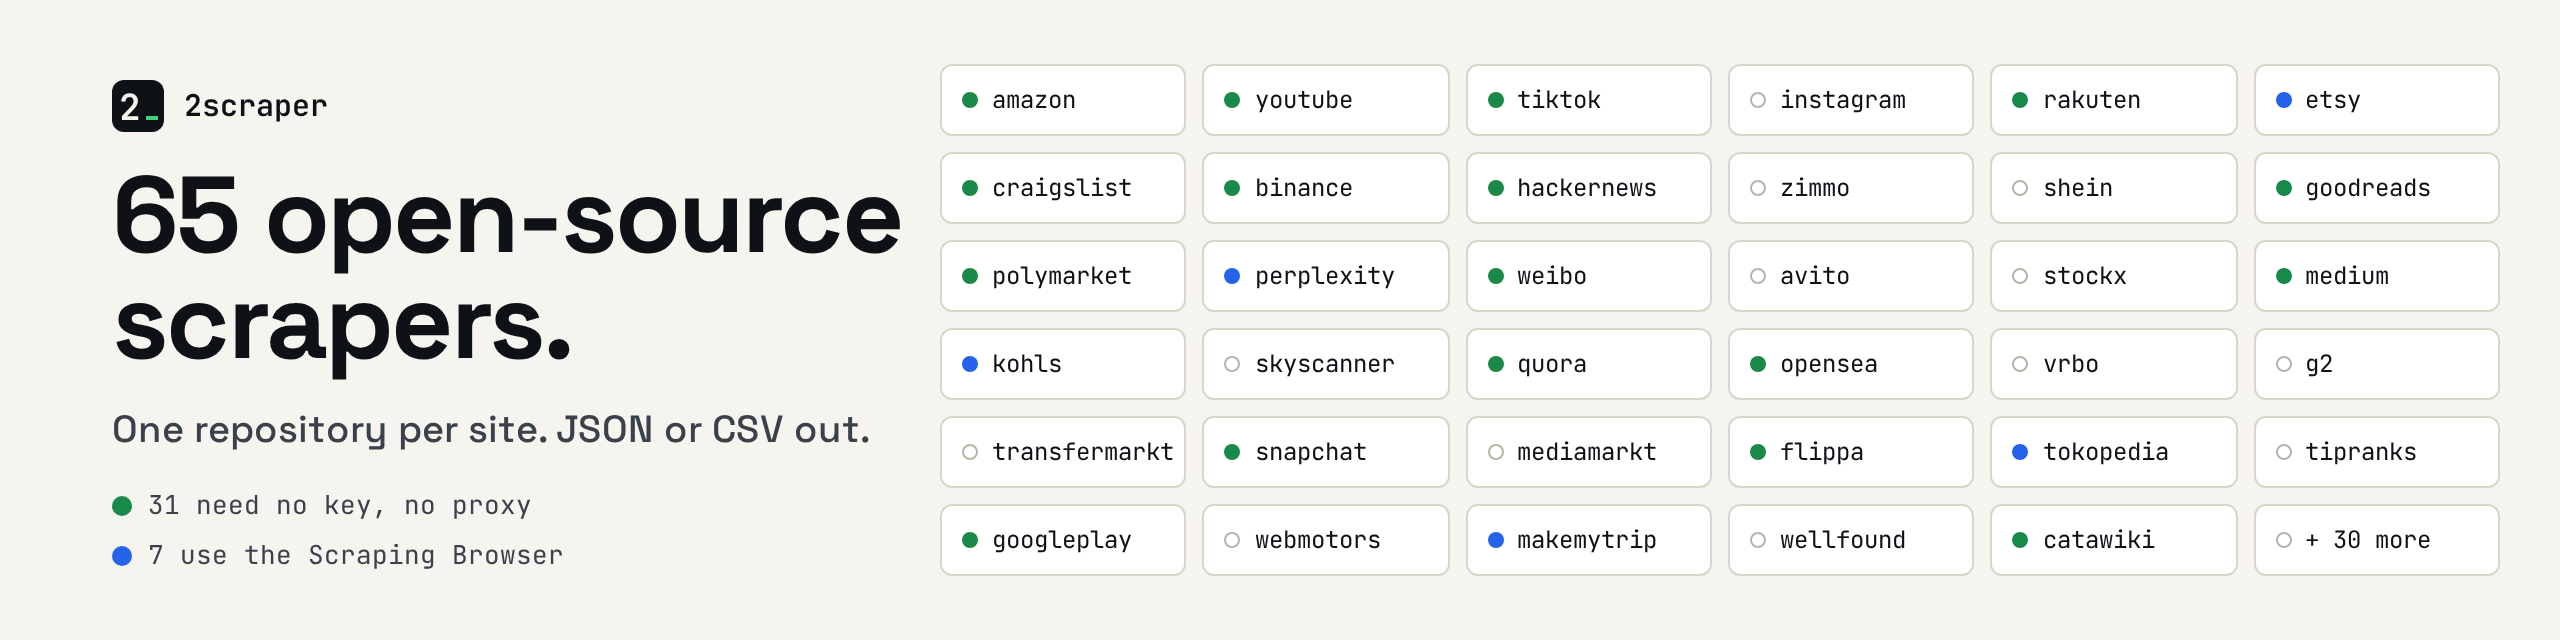
Open-source web scrapers for real-world websites.
Turn products, listings, comments, prices, and market data into clean JSON or CSV.
Browse scrapers · Request a website · Contribute


2scraper is a collection of focused, ready-to-run scrapers for popular websites. Each repository targets one platform and documents the supported pages, captured fields, setup, and output—so you can spend less time reverse-engineering websites and more time using the data.
| ⚡ Ready to run Clone a repository, follow its quick start, and collect data on your own infrastructure. |
📦 Structured by default Predictable records in JSON or CSV, with schemas and sample output where available. |
| 🧰 Multiple execution paths Playwright, Selenium, Puppeteer, the site's own JSON endpoints, or the 2Captcha Scraping Browser API—depending on the target. |
🛡️ Built for real websites Pagination, dynamic content, proxies, fingerprints, and CAPTCHA flows where the site requires them. |
- Pick a target from the scraper directory.
- Open its repository and follow the quick-start guide.
- Run locally, then add the optional browser, proxy, or CAPTCHA setup documented for that target.
Support differs by repository. The README in each scraper is the source of truth for engines, locales, fields, and infrastructure requirements.
| Repository | What it extracts |
|---|---|
| Amazon | Search results, best sellers, product pages, and public reviews across 21 marketplaces — runs with no key or proxy |
| YouTube | Comment threads and replies, video metadata, and video search — runs with no key or proxy |
| Catawiki | Auction lots, bids, reserves, estimates, and seller data — runs with no key or proxy |
| StockX | Products, asks, bids, last sales, and market statistics |
| Transfermarkt | Player profiles, market values, club squads, and transfers |
| Medium | Stories, authors, publications, tag feeds, and full article text — runs with no key or proxy |
All public platform scrapers, grouped by what they are used for.
🟢 runs with no API key and no proxy · 🔵 needs the 2Captcha Scraping Browser API — both measured and dated in that repository's README.
One platform can take more than one scraper. TikTok gates each route differently, so it is covered by four that work side by side: profiles 🟢, videos 🟢 and the EU Ad Library 🟢 need no key at all; TikTok Shop 🔵 is behind a captcha and needs the Scraping Browser. Facebook works the same way: Pages, Marketplace and the Meta Ad Library are three scrapers, all read logged out.
| Scraper | What it extracts |
|---|---|
| Amazon 🟢 | Search results, best sellers, product pages and reviews |
| Andie Swim 🟢 | Swimwear listings, per-size stock and prices |
| Bershka | Inditex catalogue, one row per SKU |
| Catawiki 🟢 | Auction lots, bids, reserves, estimates, sellers |
| Etsy 🔵 | Search, category, shop and listing pages |
| Farfetch | Fashion listings and product pages with prices |
| Givenchy 🟢 | Beauty products and prices |
| Home Depot | Category listings and product pages, prices, specs |
| Kohl's 🔵 | Category, search and product pages: prices, ranges, sale labels, per-SKU stock |
| LG 🟢 | Catalogue models, sizes and categories |
| Lidl | US grocery products, prices, unit prices |
| Maison KOSÉ 🟢 | Japanese cosmetics: products, prices, brands, stock |
| MediaMarkt | Electronics listings and product pages, prices |
| Montblanc 🟢 | Per-market prices, stock, collections, variants |
| Pottery Barn | Category listings with price ranges, then every SKU's price, markdown and stock |
| Rakuten 🟢 | Ichiba products, prices, points, shops, reviews |
| SHEIN | Search, category and product pages: prices, discounts, ratings, stock |
| Sleep Number | Smart beds and mattresses: per-size prices, ratings |
| StockX | Sneaker listings and products: asks, bids, last sale |
| TikTok Shop 🔵 | Products, prices, units sold, sellers |
| Tokopedia 🔵 | Indonesian marketplace: search, category, product pages |
| Tractor Supply 🔵 | Farm and ranch listings: per-store prices, stock, ratings |
| Woolworths 🟢 | Supermarket products, prices, unit prices, specials |
| Scraper | What it extracts |
|---|---|
| Autotrader | US car listings and detail pages: price, KBB fair price, VIN, dealers |
| Avito | Russian classifieds: listings, item pages and seller profiles, prices |
| Craigslist 🟢 | Classified listings and postings |
| dubizzle | UAE classifieds: cars, property, jobs |
| Facebook Marketplace | Listings by keyword, category, location and price, read logged out |
| Flippa 🟢 | Online businesses, websites, apps and domains for sale |
| MakeMyTrip 🔵 | Indian hotel listings: nightly prices with taxes and fees, star and guest ratings |
| Rosreestr | Russian property registry: cadastral value, area, rights and encumbrances |
| Skyscanner | Flight searches: itineraries, prices, airlines and times |
| Spinny 🟢 | Used-car listings and car pages, prices |
| Vrbo | Vacation-rental search grids and property pages |
| Webmotors | Brazilian car and motorcycle listings and adverts: price, FIPE value, market-price range, mileage, seller |
| Zimmo | Belgian property listings: prices, area, bedrooms, EPC |
| Scraper | What it extracts |
|---|---|
| foodpanda | Restaurant listings, ratings, cuisines, deals |
| Scraper | What it extracts |
|---|---|
| Facebook Pages | Contacts, followers, exact likes and latest posts with engagement |
| Google Play 🟢 | App listings, search, installs, ratings and reviews |
| Public profiles and posts: followers, likes, comments, captions, media | |
| Meta Ad Library | Ads by keyword or advertiser, EU/UK reach and targeting, political spend |
| Snapchat 🟢 | Public profiles, subscriber counts, Spotlight views and engagement, stories and highlights |
| TikTok Ad Library 🟢 | EU ads: advertisers, creatives, run dates, audience bucket |
| TikTok profiles 🟢 | Exact follower, like and video counts, bio |
| TikTok videos 🟢 | Captions, engagement, hashtags, subtitles, media URLs |
| Weibo 🟢 | Hot feed, account timelines, comments, engagement |
| YouTube 🟢 | Comment threads and replies, video metadata, search |
| Scraper | What it extracts |
|---|---|
| Goodreads 🟢 | Lists, author books, search, full book pages, every review |
| Hacker News 🟢 | Story lists, whole comment trees and user profiles |
| Medium 🟢 | Tag feeds, archives, author pages, full story text |
| Perplexity 🔵 | Pages and Discover articles: authors, cited sources, view counts |
| Quora 🟢 | Answers from questions, profiles and topics |
| Scraper | What it extracts |
|---|---|
| BBB | Business listings, BBB ratings, accreditation, complaints |
| G2 | Software categories, reviews and pricing pages: both rating scales, review counts |
| Just Join IT 🟢 | IT job offers with salaries, skills, seniority |
| Mercor 🟢 | Contract roles, rates, eligibility, corporate openings |
| Wellfound | Startup jobs with salary and equity ranges |
| Scraper | What it extracts |
|---|---|
| Binance 🟢 | P2P adverts, copy-trading lead portfolios, announcements |
| Google Finance 🟢 | Quotes, financials, analyst ratings, OHLCV, FX |
| Indiegogo 🟢 | Campaigns, funding totals, backers, reward tiers |
| OpenSea 🟢 | NFT floor prices, offers, sales history, rankings |
| Polymarket 🟢 | Prediction-market prices, order books, token ids |
| Screener 🟢 | Indian stock screens and sector listings: price, P/E, market cap, ROCE |
| TipRanks | Smart Score, analyst consensus and price targets per ticker |
| Scraper | What it extracts |
|---|---|
| Transfermarkt | Market values, squads, transfers, player profiles |
Most repositories include:
- a runnable Python implementation and command-line examples;
- JSON and CSV output with documented fields;
- sample records for a quick look at the data;
- pagination and dynamic-content handling tailored to the target;
- optional 2Captcha integrations — captcha solving, the Scraping Browser API, 2prx residential proxies and fingerprints — when a site needs them.
Every scraper can be used on your own infrastructure. Paid services are optional unless a repository explicitly says otherwise.
Every scraper runs on your own machine first. When a site pushes back, each repository says which of these helps — and which does not — with the measurement behind it.
| Product | What it gives a scraper | Where it matters here |
|---|---|---|
| Scraping Browser API | A managed Chrome over CDP with its own exit country, persistent profiles and captcha auto-solve — no browser or residential address of your own | The 🔵 scrapers, and any server-side pipeline that cannot run a headful browser from a home address |
| Captcha solving | Tokens for reCAPTCHA, Cloudflare Turnstile and other challenge widgets | Sites that put a challenge widget in front of their pages |
| Residential proxies | Residential exits by country | Sites that refuse datacentre addresses — the repositories without 🟢 say so |
| Fingerprints | A consistent, self-consistent browser identity | Volume across many sessions |
The four are billed separately; one 2Captcha account covers them.
If the target is not listed, open a scraper request with the website, pages you need, desired fields, and expected scale. For a private or custom extraction project, start an inquiry.
- Found a bug? Open an issue in the affected scraper repository and include the URL, command, and relevant log output.
- Want to improve a scraper? Fork the repository and send a focused pull request.
- Missing a platform? Request it here.
Please use scraped data responsibly and follow the target website's terms and applicable laws.
Built for developers and data teams who would rather use the data than fight the page.